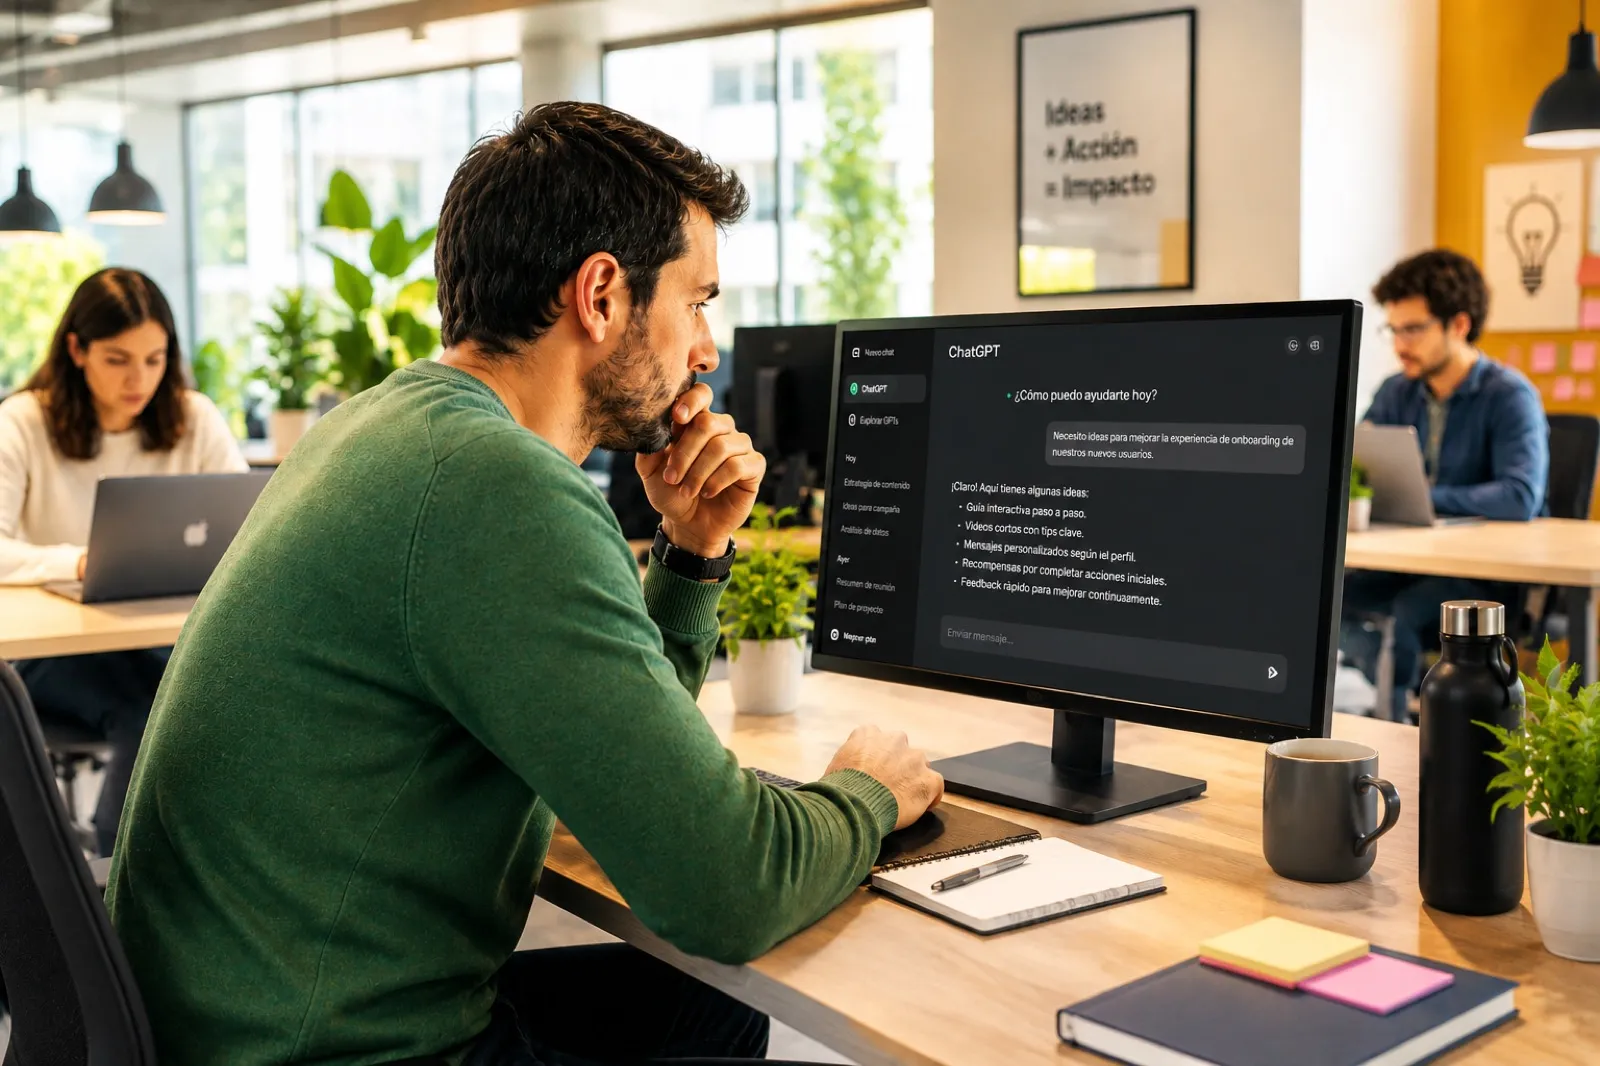
Artificial intelligence has become part of organisations' day-to-day work at unprecedented speed. Yet behind the productivity and automation lies an uncomfortable question that many companies still cannot answer: where does their data really end up, and what control do they retain over it once it leaves the company?
AI is already inside companies
Tools such as OpenAI ChatGPT or Microsoft Copilot have entered organisations much faster than other technologies. In many cases there has been no planned adoption process. Employees have simply started using them on their own initiative to speed up tasks, summarise documents or generate content.
Today it is common for workers to enter contracts, sales proposals, internal reports or customer information into external artificial intelligence systems in search of speed and efficiency, often without being aware of the implications of sharing that kind of information outside the corporate environment. The problem is that most companies have no real visibility over that use, and do not know which tools are being used or what data is leaving the organisation every day.
Does ChatGPT train on my company's data?
It depends on which account is used, and this is one of the most common sources of confusion within organisations. On free and Plus accounts, OpenAI uses conversations by default to improve its models, unless the user manually switches off that option in their data controls, as explained in OpenAI's own privacy policy. On the corporate ChatGPT Team and ChatGPT Enterprise accounts, conversations are contractually not used to train models. This difference matters because many companies assume they "already use the paid version" when in reality their employees are still working with personal Plus accounts, without any of the contractual guarantees of an Enterprise account.
Paying for an Enterprise version does not make the risk disappear
Subscribing to an enterprise version reduces the risk, but does not eliminate it. There are frequent situations that can break the service guarantees without the company being aware of it. One of the most common is several team members sharing the same corporate account, something common in small companies looking to cut costs. Sharing credentials not only goes against the terms of use of most providers, it also removes traceability: if something goes wrong, there is no way of knowing who did what. The solution is not to ban the tool, but to give each person an individual account within a team plan, which is precisely what those plans exist for.
The lesser-known warning: Copilot does not train on your data, but it can still expose it
With Microsoft Copilot the risk is of a different nature and, for many companies, more immediate. Microsoft is clear that the organisation's data is not used to train its AI models without explicit consent, according to its own Microsoft 365 Copilot privacy documentation. The real problem is a different one: Copilot surfaces, in a natural-language answer, any document or email that an employee already has technical access to, even if they would never have found it by browsing manually. If a Human Resources folder was shared with "all employees" three reorganisations ago, or if a link for a one-off project was left open to the whole company, Copilot makes it perfectly easy to find with a simple question. Microsoft openly acknowledges this and offers specific tools, such as Microsoft Purview, to audit and correct these permissions before rolling out Copilot at scale, according to its own secure deployment guide. In practice, this means that switching on Copilot without first cleaning up SharePoint and Teams permissions exposes years of careless configurations in one go.
Feedback can expose entire conversations
Another little-known aspect concerns the feedback users voluntarily send to the platforms. Many people use options such as "improve response" or share conversations to report incorrect results, without fully understanding what that action involves. On non-corporate accounts, that process may allow the entire conversation to be reviewed and used to train new models, including prompts, copied documents or any other content shared during the interaction. Although these conditions are usually set out in the service policies, very few users read them in detail, and even fewer companies train their employees to understand them.
Big Tech is not infallible either
There is a perception that large technology companies always operate within completely safe legal margins. Recent events prove otherwise. In December 2024, the Italian data protection authority (the Garante) fined OpenAI 15 million euros for processing personal data to train ChatGPT without an adequate legal basis and for failing to inform users properly, as reported by Xataka. Meta, for its part, has accumulated more than 1.1 billion dollars in data protection fines since 2021, according to data compiled by Termly. This does not mean that all platforms act irresponsibly, but it does show that the existence of regulation does not automatically eliminate every risk, and that delegating the protection of corporate knowledge to third parties without understanding how these platforms really work can be a dangerous decision in the medium term.
Why do the big tech companies need access to our private content?
The major artificial intelligence providers constantly need new sources of information to keep improving their models, and the public content on the internet is starting to run out. According to estimates by the research organisation Epoch AI, reported by Xataka, the high-quality text available on the internet could run out between 2026 and 2032, because current models have already been trained on most of the quality public information available. That is why private content has become a strategic asset: users' conversations, companies' internal documents and everyday interactions with AI tools represent far more valuable knowledge than much of the generic internet content already exploited. Therein lies one of the keys to the current race to lead artificial intelligence, and also the reason why every conversation, every prompt and every corporate interaction has a value that goes beyond the immediate productivity of the employee who generates it.
The real problem is the lack of control
Most organisations still have no clear policies on artificial intelligence. They do not know which tools their employees use, what information can be shared or which uses should be prohibited. In many cases there are also no processes for oversight, traceability or classification of the sensitive information entered into these platforms. AI is being incorporated into organisations faster than companies are able to govern it, and that is where the real risk lies: it is no longer simply an office tool, but an interface for accessing the company's internal knowledge, including strategic documentation, know-how, financial information and intellectual property.
What an internal AI use policy should include, at a minimum
Before banning it or letting anything go without criteria, an organisation needs to answer a handful of specific questions: which tools are permitted and which are not; what type of information may be entered and what is expressly prohibited, such as customer data, contracts or proprietary code; how accounts are managed, always avoiding shared credentials; and who trains the teams, because most information leaks are not malicious but the result of a lack of awareness. It is also worth bearing in mind the European regulatory framework: the EU AI Act, progressively in force since 2024, adds transparency and human oversight obligations on top of those already existing under the GDPR, especially when AI takes part in decisions that affect people.
Productivity is no longer the only priority
For months, the discourse on AI has focused almost exclusively on productivity and automation. The real debate starts now: companies need to decide how to incorporate this technology without losing control over their data and their internal knowledge. That means establishing usage policies, training teams, reviewing contracts and understanding how the platforms really work. In many cases, organisations will end up needing private environments or controlled models that allow them to harness the advantages of artificial intelligence without exposing critical information to third parties. The question is no longer whether companies are going to use AI, but how much corporate knowledge they are willing to hand over in exchange for convenience and speed.
Conclusions and recommendations
Artificial intelligence cannot enter a company without rules, nor depend solely on the individual judgement of each employee. If an organisation allows its teams to work with tools such as ChatGPT or Copilot, it needs to set clear limits from the outset: which tools can be used, what information can be shared, how accounts should be managed and what risks the company takes on by entering corporate knowledge into external platforms.
In organisations that work with sensitive information, intellectual property or strategic processes, the solution usually involves adopting private AI models: systems deployed in environments controlled by the company itself, where data, conversations and internal knowledge remain under its control. And in any case, before taking that step, it is advisable to start with an AI consultancy engagement that audits which tools are being used today, what risks really exist and what internal policy the organisation needs. This makes it possible to harness the advantages of artificial intelligence without depending entirely on external public platforms or exposing the organisation's critical information.
CEO of LurNova, with extensive experience in technology and digital transformation. Involved in developing technology projects and applying artificial intelligence in organisations, he combines technical knowledge with business vision.